 梦兽编程™AI_SUITE
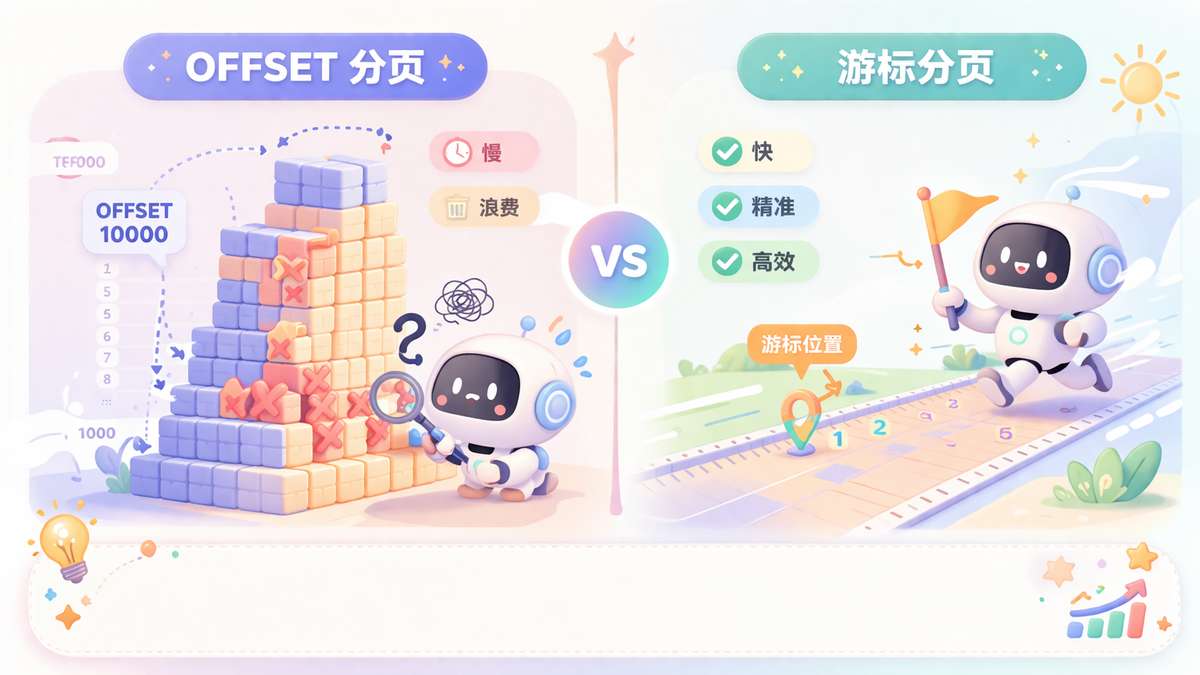
Ever noticed how your paginated lists load fast at first, then slow down noticeably as users scroll deeper into the results?
Coworkers blame the database. Product says upgrade the hardware. The DBA shrugs and suggests more RAM.
Nothing changes.
The real culprit is usually sitting in plain sight — your pagination strategy.
The Honest Truth About OFFSET
OFFSET looks clean and reads naturally:
SELECT * FROM posts
ORDER BY created_at DESC
LIMIT 20 OFFSET 10000;
Page 1 is fast. Page 10 is acceptable. Page 500?
The database is counting.
It scans the first 10,000 rows, then hands you the 20 you actually asked for.
You requested 20 rows. The engine scanned 10,020. You’re only seeing the tip of the iceberg.
Why It Gets Worse — And It’s Not the Database
Think of a librarian searching for books on a shelf.
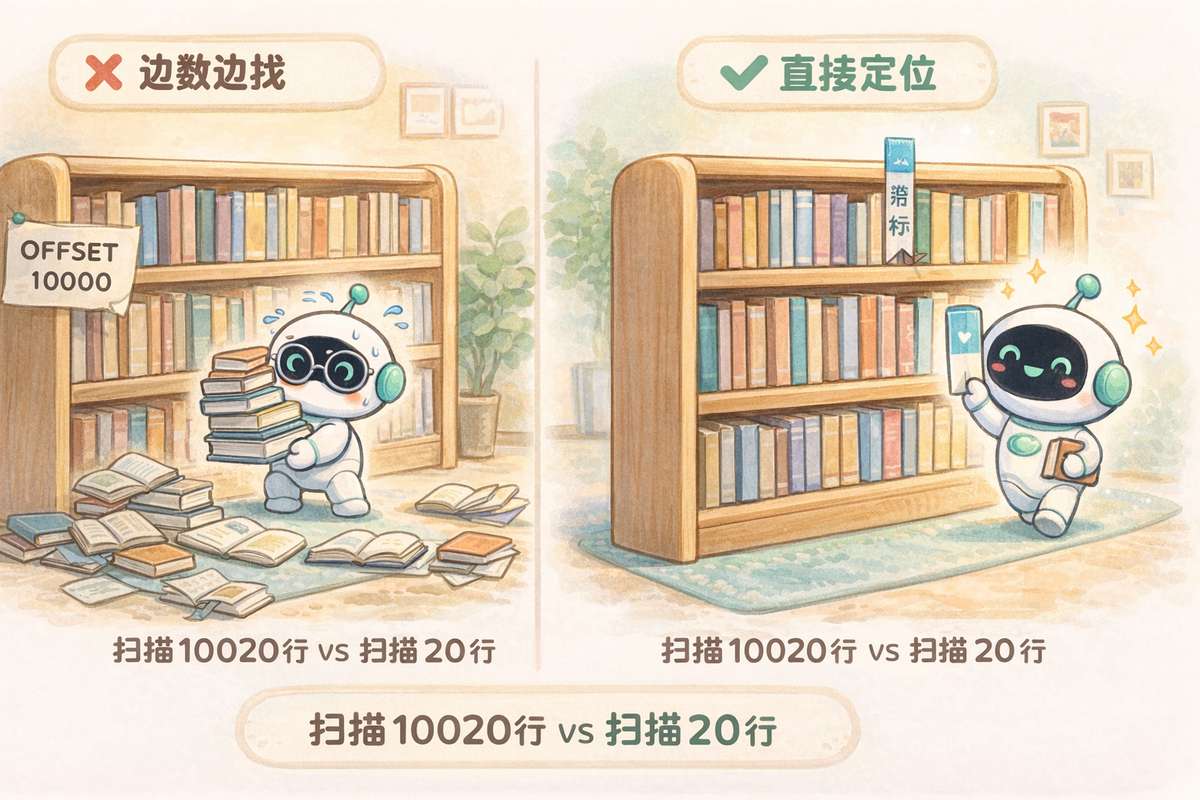
With OFFSET, the librarian starts counting from shelf 1, counts all the way to shelf 500, then hands you that page’s books.
Page 1: counted 0 books, done. Page 500: counted 10,000 books, then gives you 20.
Users feel “slow.” Nobody sees the counting happening in the background.
The problem compounds over time.
More rows → deeper offsets → more skipped rows → higher latency.
Your product is growing. Your queries are getting slower. This is a self-reinforcing trap.
The Hidden Correctness Problem Nobody Talks About
OFFSET isn’t just slow — it’s unstable.
Picture this: a user scrolls from page 1 to page 10.
While they’re scrolling, new rows get inserted.
The starting position of page 10 shifts. One row disappears. Another reappears.
Users see duplicates and gaps.
They won’t say “offset pagination is unstable under concurrent writes.”
They’ll say: “Is this list broken?”
They’re right.
The Librarian Analogy: Two Ways to Find Books
OFFSET = start from the beginning and count your way to page N.
Keyset = remember where you left off, and continue from there.
The second approach is faster and more stable. It never goes back to count.
Cursor Pagination: Start from Where You Left Off
Keyset pagination (also called cursor pagination) changes the question entirely.
Instead of: “Give me page 500.”
You say: “Give me the next 20 rows after this one.”
-- Previous page's last row: created_at = '2026-03-20 15:00:00', id = 12345

SELECT id, title, created_at
FROM posts
WHERE (created_at, id) < ('2026-03-20 15:00:00', 12345)
ORDER BY created_at DESC, id DESC
LIMIT 20;
The (created_at, id) pair is your cursor.
The id handles tie-breaking when timestamps collide. Together they form a stable, unambiguous position.
Why Keyset Is Fast: The Index Does the Work
The magic is in the composite index that matches your query shape:
CREATE INDEX posts_created_id_desc_idx
ON posts (created_at DESC, id DESC);
The index order matches your query’s ORDER BY. The database seeks directly to the cursor position, then reads the next 20 rows sequentially.
No counting. No full scans.
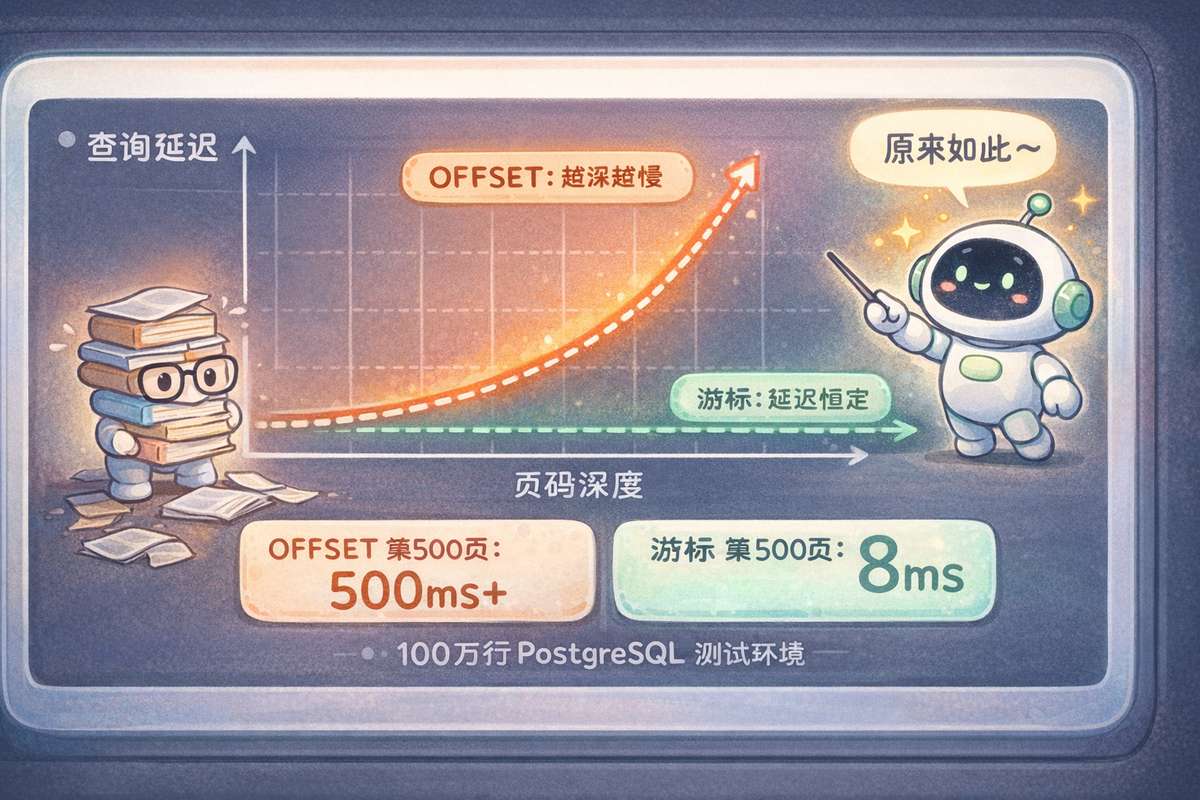
Latency becomes predictable — it no longer degrades with page depth.
Real-world tests on a 1M-row table: OFFSET page 500 is typically 50x slower than page 1. Keyset keeps page 500 within 2x of page 1.
What Makes a Good Cursor?
Common choices:
created_at + id: best for feeds, activity logs, event streamsidalone: works for strictly monotonic primary keys- Business keys: e.g.,
last_viewed_atfor custom sort logic
One rule: the cursor field must not change frequently. If the sort key mutates, pagination breaks.
The Tradeoff Nobody Talks About
This is the only real cost of switching.
OFFSET lets you jump to page 37 directly.
Keyset only moves forward or backward: “next page” or “previous page.”
Ask yourself: do your users actually need to jump to page 37?
Feeds, notifications, order histories, audit logs — these are all “keep scrolling” patterns. Nobody navigates to page 500 on purpose.
If your product truly needs page jumping, here’s a pragmatic hybrid:
- Low-traffic internal lists: keep OFFSET, page numbers are fine at small scale
- High-concurrency user-facing lists: use Keyset, stability and speed matter more
Use the right tool for the job.
Migration Checklist
Before you ship the change:
- Pick a stable sort key and add
idas a tie breaker - Build a composite index matching the exact sort order of your query
- Encode the cursor before sending it to the client (base64 JSON is sufficient)
- Return
next_cursorin the API response so clients can pass it back - Load test deep pagination paths — testing only page 1 is useless
What Changes Beyond Speed
Teams migrate for performance. They stay for reliability.
Keyset pagination also brings:
- No more list jumping under concurrent writes
- Fewer duplicate and missing row reports
- Cleaner API contracts
- Better index discipline
It also changes how engineers think about data access.
Old question: “What page is this?” New question: “Where is the next boundary?”
That’s a cleaner mental model — and the database is better at answering it too.
FAQ
At what data volume does OFFSET start to show problems?
You’ll feel it above 100K rows. Beyond 1M rows, page 500 will be noticeably slower than page 1. Hardware and concurrency affect the magnitude, but the underlying issue is always there.
Can keyset pagination jump to an arbitrary page?
No — that’s its main tradeoff. If your product genuinely needs “go to page 37” (think search engine results), keyset isn’t the right fit. Consider using OFFSET with a reasonable limit, or a hybrid approach for different list types.